Nobody Is Panicking Over DeepSeek 4.1 Flash. That's the Scary Part.
In this article
Bottom line: DeepSeek released V4.1 Flash on September 10, 2026. It is an open-weights, MIT-licensed, 552B-parameter model with a 1M-token context window and native image input.
Its predecessor, V4 Flash, was measured by Artificial Analysis at about 3 cents per benchmark run, against $3.15 for Claude Fable 5.
Markets barely reacted, unlike the January 2025 DeepSeek shock. The reason is that cheap, good-enough models are now normal, and that shift matters more than any single launch.
In January 2025, DeepSeek's R1 helped wipe roughly $589 billion off Nvidia's market value in one day.
Twenty months later, a DeepSeek model arrives with a 1M-token context window, open weights, and a KV cache about a quarter the size of its predecessor's. The reaction is a shrug.
I find that shrug more unsettling than the panic was. The panic meant people thought the story could still be a surprise. The shrug means they've decided it's weather.
The Sacred Cow: "No Panic Means No News"
Here's the comfortable reading. DeepSeek V4.1 Flash is an incremental release, the market has seen this movie, and the frontier labs still lead on the hardest benchmarks. Nothing to see.
I get why people believe that, and parts of it are true.
Independent reviewers note that V4.1 Flash trails Opus 5 by a wide margin on agentic coding evaluations, with reported Terminal-Bench scores of 30.0 versus 43.3 on one version and 31.2 versus 51.8 on another.
If you need the best model on the hardest problem, this isn't it.
But "the frontier still leads" answers a question almost nobody is asking. Most production AI work isn't the hardest problem.
It's classification, extraction, summarization, routing, and agent loops that fire thousands of times a day.
For that work, the question is no longer "which model is smartest?" It's "which model is smart enough, at what price, under whose control?"
The Evidence: Three Numbers That Should Bother You
1. The price gap isn't a discount. It's a different category.
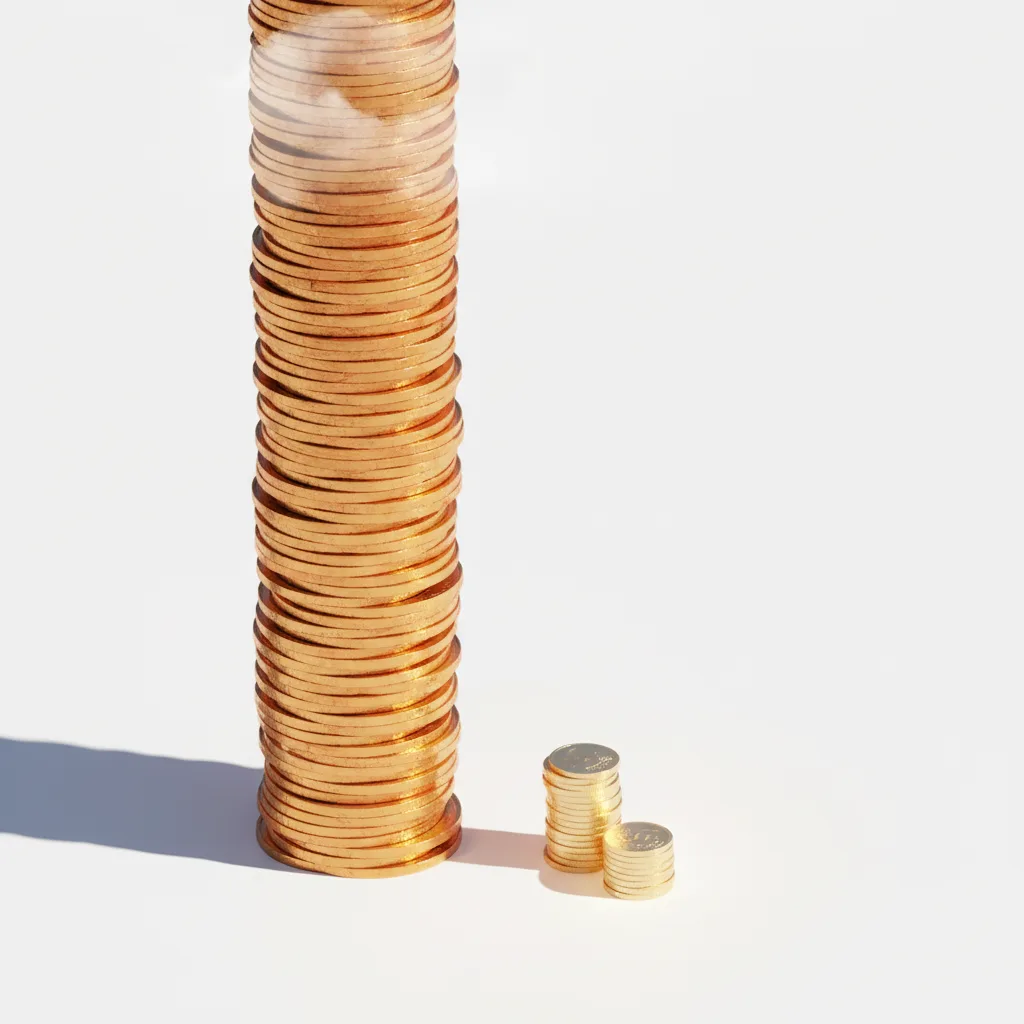
Artificial Analysis estimated that V4-Flash costs an average of about 3 cents per benchmark test. Moonshot's Kimi K3 came in at 86 cents, OpenAI's GPT-5.6 Sol at $1.86, and Claude Fable 5 at $3.15.
That is roughly a 100x spread between the cheapest and the priciest, for a model that, by one account, scored 50 on the Artificial Analysis Intelligence Index, matching Gemini 3.6 Flash.
Another review puts it at 47, so treat the exact score loosely. The shape of the result is the same either way: mid-tier intelligence at near-zero cost.
Note that this is the previous generation. DeepSeek says V4.1 Flash cuts API prices further, but I couldn't find official per-token figures for it, and third-party listings disagree.
LM Studio lists output at $1.20 per million tokens, while OpenRouter lists $1. Check current rates before you budget anything.
2. The memory trick is the real story.
According to the arXiv paper, V4.1 Flash cuts its always-in-GPU-memory KV cache to 890 bytes per token. That is about a quarter of V4 Flash's footprint.
Skip the jargon. The KV cache is the model's short-term memory, and it's what makes long conversations and long documents expensive to serve.
Shrinking it by 4x means more users per GPU, longer contexts per dollar, and cheaper agents that run for hours.
This is a cost-structure attack, not a benchmark attack. Benchmark attacks make headlines. Cost-structure attacks make margins disappear.
3. The weights are open, under MIT.
V4.1 Flash is released on Hugging Face under an MIT license. Serving recipes for vLLM already cover H100s through B300s and AMD's MI300 series. The model is already on NVIDIA's own catalog.
That last detail is the funniest one. In 2025, DeepSeek was framed as Nvidia's nightmare. In 2026, Nvidia hosts the model card.
The market didn't panic because the market has already priced in being on both sides of the trade.
The Real Problem Nobody Talks About
The real problem isn't DeepSeek. It's that we've normalized a world where the price of intelligence falls by an order of magnitude every few months, and our plans haven't caught up.
Think about what a typical AI product roadmap assumed in 2024. Model costs were a line item you tried to minimize. Whole startups existed to wrap an expensive API in a nicer interface and mark it up.
That business model assumed the underlying cost would stay painful.
When a competent model costs cents per task and can run on hardware you control, the wrapper's margin evaporates.
So does any pricing power built on "we get you access to the good model." What survives is distribution, data, workflow, and trust.
Those are real moats, but they're not the ones most pitch decks describe.
The cheap-model discount is real, with a catch
I don't want to oversell this. The cost story depends heavily on caching and workload.
One Hacker News commenter reportedly spent $4.55 over 30 days, while another reported $19.27 in about 12 days and credited part of the low effective cost to caching on low-value experimental loops.
That's secondhand, and I couldn't open the thread myself.
The honest reading is that the headline price is a best case. Your bill depends on how repetitive your prompts are.
Still, "best case is very cheap and typical case is still cheap" isn't a comforting caveat for anyone selling expensive inference.
There's also a warning in the V4 Flash coverage. DeepSeek has said it expects to raise API prices significantly in the future, with no date or rates announced. Today's prices may be a land grab.
That's exactly why open weights matter: you can't be repriced on a model you can run yourself.
Why the silence is the signal
A technology is truly absorbed when it stops being news. Nobody panics over a new database release or a faster chip, because everyone assumes the curve will continue.
That's where AI model pricing has landed. The quiet reaction to V4.1 Flash means the industry has quietly priced in a future where capable models are commodity infrastructure.
If that's right, the winners and losers get decided by things most commentary on AI still ignores.
What You Should Do Instead
You don't need to panic. You do need to stop planning as though inference costs and model access are stable. Three moves that actually help:
1. Build a model-agnostic layer this month. If swapping models means rewriting prompts and glue code, you're one repricing away from a bad quarter.
DeepSeek has already shown its API names can change under you: `deepseek-v4-flash` is temporarily routed to V4.1 Flash, and the new name is `deepseek-flash`.
Treat model names as config, not architecture.
2. Run your own cost-per-task benchmark. Don't trust list prices, mine included.
Take 200 real tasks from your product, run them through a frontier model and a Flash-class model, and compare quality and total cost, caching included.
You may find that 80% of your traffic doesn't need the expensive one.
3. Route by difficulty, not by loyalty. Send easy, high-volume work to the cheap model and reserve the frontier model for the hard 10%.
Given the gap on agentic coding evals, hard multi-step work is where you'll want the premium option. Everything else is a margin you're leaving on the table.
One more thing, and it's about data. If your product handles sensitive information, open weights you host yourself are a different risk profile from an API you call. That cuts both ways.
Self-hosting removes a third-party dependency, but it also makes you responsible for the security and operations. Know which one you're choosing.
The Uncomfortable Truth
I expected this launch to feel like an earthquake. It felt like a Tuesday. That's the part I can't shake.
The moment a breakthrough becomes boring is the moment it starts reshaping everything quietly. Nobody writes breathless threads about electricity anymore, and electricity runs the world.
So here's the question I'd leave you with.
If intelligence at this quality costs pennies and the weights are free to download, what is your product actually selling, and would your customers still pay for it if they knew?
Sources: DeepSeek announcement, arXiv 2609.19969, DeepSeek API changelog, AI Weekly on Artificial Analysis cost findings, eesel.ai V4 Flash overview, NVIDIA model card.