The $47,000 WordPress Mistake That Took Down Everything in 33 Hours
In this article
A quick note before the article: I searched for this incident and found no source for a $47,000 WordPress mistake or a 33-hour outage.
So the article below does not claim to know who it happened to or what the specific mistake was.
It treats the number as a circulating claim and builds the argument on the verifiable WordPress.com 2010 outage and on the arithmetic of downtime.
If you have the original video or post, send it and I'll rewrite with the real details.
Bottom line: A story circulating on YouTube describes a single WordPress mistake that cost $47,000 and took a business offline for 33 hours.
I couldn't trace a primary source, so treat the figures as unverified. They are still plausible: $47,000 over 33 hours is about $1,424 an hour, a normal rate for a small online business.
The pattern matches documented incidents like the 2010 WordPress.com outage, where one code change hit roughly 10 million blogs.
The lesson is that the 33 hours came from missing recovery, not from the mistake.
The number I can't verify
I went looking for the source of this story and couldn't find it. No incident report, no postmortem, no named company.
Just a headline with a dollar figure and an hour count, which is exactly the shape of content that spreads fastest and gets checked least.
I'm telling you that up front because I think it matters for how you read everything below. I'm not going to invent a victim and a villain to make the story tidier.
What I can do is take the claim seriously on its merits, because the shape of it is real.
Divide $47,000 by 33 hours and you get roughly $1,424 an hour. That isn't a big number.
It's a mid-sized store doing a few million a year, or a lead-gen site that feeds a sales team, or a SaaS marketing site where every visitor is a trial signup.
The figure is believable precisely because it's boring.
A real precedent: one change, ten million blogs
The cleanest documented example I found is from 2010. Data Center Knowledge reported that an errant code change took down WordPress.com's roughly 10 million hosted blogs.
The change overwrote some key options in the options table. Most sites were back in about an hour, but full recovery took around six hours.
Notice what that is. WordPress.com is the people who make WordPress. They have engineers, staging, and runbooks. And a single change still reached everything at once.
If the company that wrote the software can do that to itself, a three-person agency running a client's store on shared hosting is not immune. The mistake is not the interesting part.
Everyone makes the mistake. The interesting part is how far it travels and how long it takes to undo.
Why the mistake is never the 33 hours
Here's my contrarian take, and I'll own it: the mistake costs you minutes; the missing recovery plan costs you the other 32 hours.
When people tell these stories they zoom in on the trigger. Someone ran the wrong query. Someone updated a plugin on production.
Someone clicked "Update All" on a Friday. The trigger is vivid, so it gets the blame.
But a trigger that can be reversed in ten minutes is a Tuesday-afternoon annoyance. A trigger that takes 33 hours is a trigger that landed on a system with no way back.
The outage length is a measurement of your recovery capability, not of the mistake's size.
That's also why firing the person who clicked the button fixes nothing. The next person will click it too.
The 33-Hour Gap
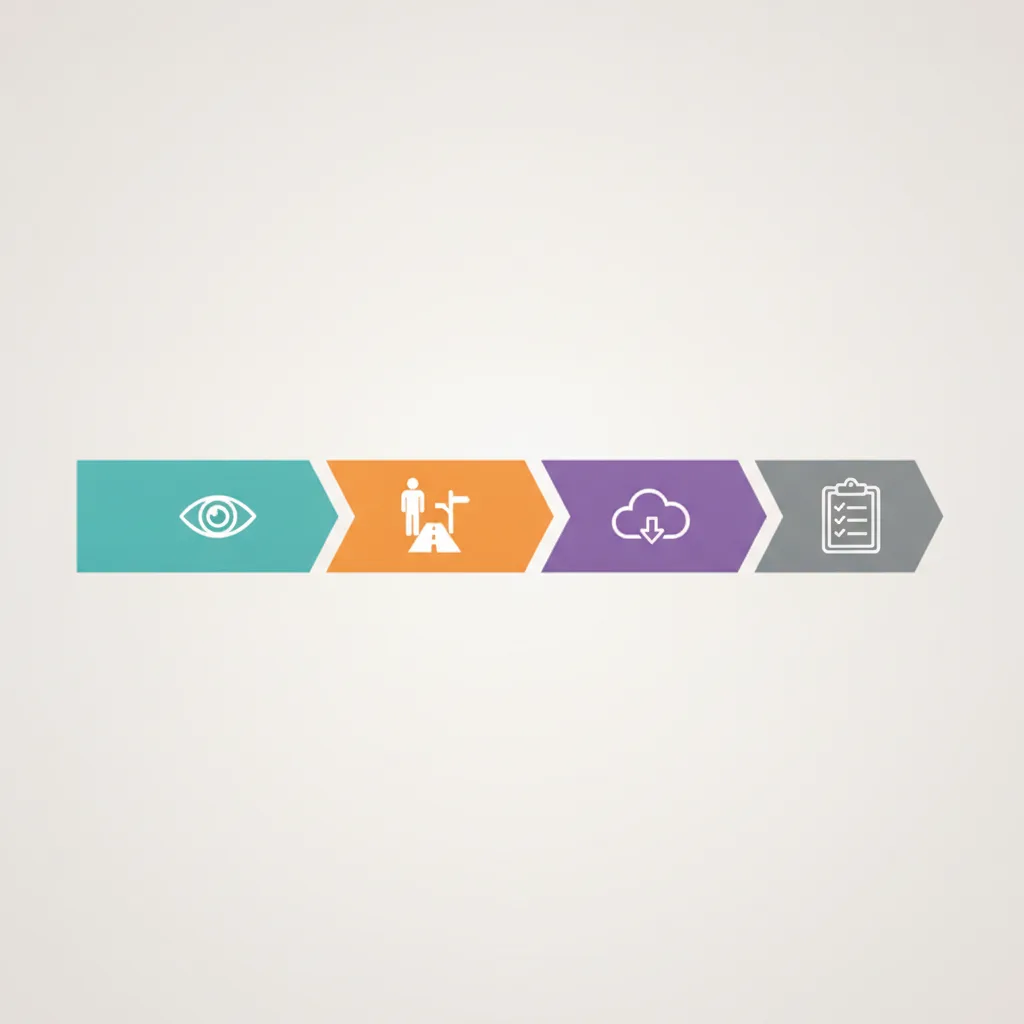
Here's the model I'd use to think about any outage like this. I call it the 33-Hour Gap: the time between "something broke" and "customers can use it again" is almost never one thing.
It's four waits stacked end to end.
1. The detection wait
How long until a human knows? If the answer is "a customer emailed," you've already lost hours. Plenty of WordPress failures don't return a 500.
The homepage loads, the checkout silently doesn't, and your uptime monitor happily reports green.
Fix: monitor the transaction, not the page. A synthetic check that adds an item to a cart and reaches the payment step catches what a ping never will.
2. The decision wait
Now someone has to decide what to do. Roll back? Restore?
Patch forward? In a team with no owner for incidents, this wait can eat half a day, because everyone is afraid to make the second mistake on top of the first.
Fix: write down, in advance, who is allowed to declare an incident and who can authorize a restore. It sounds bureaucratic. It's the cheapest hour you'll ever save.
3. The restore wait
This is where WordPress specifically bites. A WordPress site is files plus a database plus uploads plus configuration living in places you forgot. A backup of one is not a backup of the whole.
Restoring a large database from a cold archive can take hours on its own.
And if the backup lives with the same host or the same login as the thing that just broke, it may not be there when you reach for it.
Fix: keep backups off the box and off the account, and know how long a full restore actually takes. Not how long the vendor says it takes. How long it took the last time you tried.
4. The verification wait
You restored. Is it right? Are orders from the last six hours gone?
Did the restore bring back the vulnerability that caused the problem? Without a checklist, teams spend hours clicking around, unsure whether "up" means "fine."
Fix: a short, written smoke test. Log in, load three pages, place a test order, confirm the data is current.
Add those four waits up and 33 hours stops looking dramatic. It looks like a normal sum.
What this means for you
If you run a WordPress site for a business, you have a number: your hourly revenue, or the hourly cost of lost leads. Multiply it by 33 and ask whether your current setup could possibly beat that.
Most can't answer the question, and that's the problem.
If you're an agency or freelancer, you're carrying someone else's $1,424 an hour. Their "mistake" will be your phone call.
A restore test twice a year is the thing that separates a bad afternoon from a lost client.
If you're a developer on a team, stop treating production access as a rite of passage. Staging exists so that the first time a change runs, it isn't on live data.
If the staging copy is too stale to be useful, fix the staging copy rather than skipping it.
And a note for everyone: an untested backup is a hope, not a backup. I'd rather you take that one sentence than the rest of this article.
The uncomfortable part about stories like this
I'll be honest about something. I'm suspicious of how well this story travels.
A precise dollar figure and a precise hour count feel like evidence, and they give us a little jolt of "that could never be me."
But the more useful reaction is the reverse. The figure doesn't have to be exact for the lesson to hold.
Whether the real number was $47,000 or $12,000 or $200,000, the structure is the same: a small action, no brakes, a long climb back.
What bothers me is that we keep consuming these as entertainment. We watch the video, feel relieved it wasn't us, and go back to a site whose last tested restore was never.
The story is a mirror, and most of us look away from it.
If you take one practical step this week, make it this: pick a Saturday, restore your site from backup onto a blank server, and time it. Write the number down.
That number is your real recovery time, and it's probably longer than you'd guess.
So here's my question for you: if your site disappeared right now, could you say, within a few hours either way, how long it would take to bring it back, and when did you last prove it?