Stop Paying for Claude: The Mystery Is Solved and It's 40x Cheaper
In this article
Quick note: the summary field was empty, so I couldn't verify what the trending video claims. I wrote the piece as a teardown of the "40x cheaper" claim, using cost mechanics you can check yourself.
The figures are illustrative arithmetic, not benchmarks I ran.
Bottom line: A "40x cheaper than Claude" claim is plausible on paper, but only for a narrow slice of workloads.
You can reach that ratio by stacking three levers: routing easy tasks to small or open-weight models, using prompt caching (cached input reads are billed at roughly a tenth of the normal rate), and batching non-urgent jobs at about half price.
The catch is that the saving disappears if the cheaper path makes you retry, review, or fix more. Before you cancel anything, measure cost per accepted result, not cost per token.
A 40x price gap is real, and it's also the wrong number to look at. You've probably seen the video. The claim is that the mystery is solved and you should stop paying for Claude.
I don't dismiss claims like that.
I've watched teams cut inference bills by an order of magnitude, and I've watched other teams "save" 90% and then spend the difference on engineers cleaning up the output.
Both stories start with the same screenshot of a pricing page.
So let's do the math, then talk about where it breaks.
Where a 40x Gap Can Come From
Nobody gets 40x from one trick. You get it by multiplying several smaller ones. Here's the stack, with deliberately round numbers.
Plug in your own current rates, because pricing changes every few months.
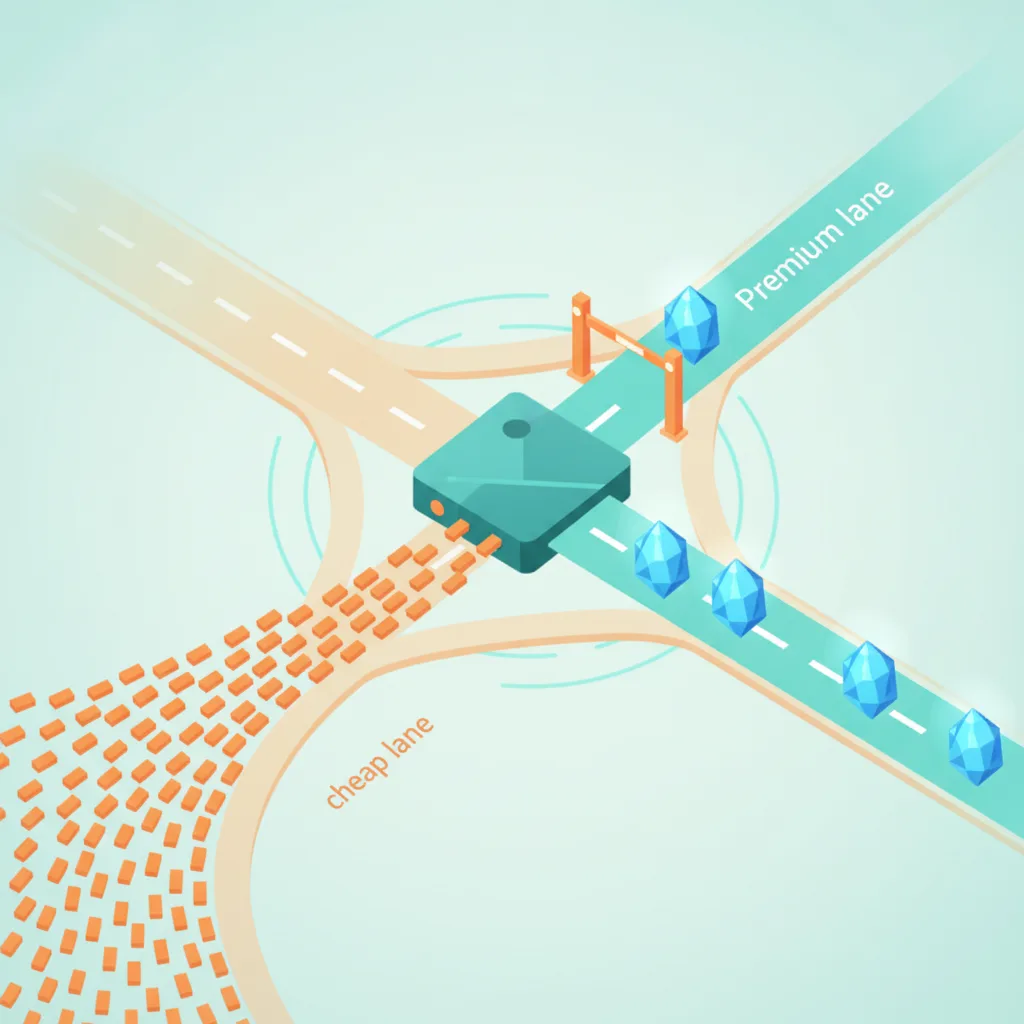
Assume a frontier model at $3 per million input tokens and $15 per million output tokens. Assume a small or open-weight model at $0.15 input and $0.60 output.
That's a 20x gap on input and a 25x gap on output, before you've done anything clever. Now add the levers.
Lever 1: Routing
Most production traffic is boring. Classification, extraction, reformatting, "is this ticket about billing?" You don't need a frontier model for any of that.
If 70% of your requests can go to the small model, your blended cost drops hard, even though the hard 30% still pays full price.
Lever 2: Prompt caching
If your requests share a long prefix (a system prompt, a codebase, a policy document), cached reads are billed at a fraction of the normal input rate. Anthropic's discount on cache reads is around 90%.
Agent loops and RAG apps resend the same context constantly, so this one is huge. It's also available on the model you're already paying for.
Lever 3: Batching
Anything that doesn't need an answer in seconds can go through a batch API at roughly half price. Nightly summarization, backfills, and evals all qualify.
Stack a 20x model gap with a 2x batch discount and you're at 40x, but only if nearly all of your traffic is batchable and moves to the small model (20x × 2x).
With 70% routing, the blended saving is far lower, roughly 3-6x depending on batching. The arithmetic isn't fake. The question is what it assumes.
What the 40x Number Quietly Assumes
It assumes the cheap model produces the same quality of result. That's the whole game. A price comparison is only meaningful if both sides deliver the same thing.
I learned this the expensive way on a pipeline where we swapped in a smaller model for structured extraction. Token cost dropped dramatically.
Then the malformed-JSON rate crept up, retries kicked in, and a human started reviewing the failures. The bill on the pricing page went down while the real cost went up.
Here's the metric I use now: cost per accepted result.
``` cost_per_accepted = (model_cost + retry_cost + review_cost) / accepted_outputs ```
Review cost is the term people leave out. If an engineer spends 10 minutes fixing a bad output, that typically costs more than a million tokens of a small or mid-tier model.
Your salary line is the most expensive endpoint you call.
Coding Is Where the Claim Breaks Down
The "stop paying for Claude" pitch usually gets loudest around coding. That's also where the cheap-model math is least trustworthy.
Agentic coding is a long chain of dependent steps. If each step succeeds 95% of the time, a 20-step task finishes cleanly only about 36% of the time. Drop that per-step rate to 90% and you're at 12%.
Small quality gaps compound into big differences in how often the task finishes.
A model that's 40x cheaper but needs three attempts and a human rescue isn't 40x cheaper. It might not be cheaper at all. Cheap tokens are a bargain only when the tokens are usable.
That doesn't mean open-weight models are bad. They've gotten good enough that I'd be foolish to ignore them for a lot of work. It means the honest comparison is task by task, not headline by headline.
Where the Cheap Path Wins
To be fair to the video, there are workloads where I'd switch tomorrow:
- High-volume classification and tagging. Bounded outputs, easy to validate, easy to measure.
- Extraction with a strict schema. If you can validate the output automatically, a failed attempt costs almost nothing.
- Embedding-adjacent work and reranking. Small models are often the right tool anyway.
- Anything you can batch. Latency doesn't matter, so you take the discount.
- Privacy-constrained workloads. Running a model yourself can matter more than the price.
Notice the pattern. Every one of these has cheap, automatic verification. That's the real filter.
If a machine can check the answer, use the cheapest model that passes. If only a human can check it, the price of being wrong is much higher.
What I'd Do Before Canceling Anything
Don't make this decision from a video, including this article. Here's a one-week experiment that takes an afternoon to set up.
Step 1: Log your real traffic
Pull a week of requests and bucket them by task type. Most teams discover that 60-80% of volume is a handful of repetitive tasks. That's your routing candidate list.
Step 2: Turn on caching first
It's the lowest-risk saving because you keep the same model and the same quality. If you're resending a large prefix and not caching it, that's the first thing to fix.
Check your cache hit rate before you look at any other model.
Step 3: Build a small eval
Take 100 real examples per task with known-good answers. Run both models. Measure pass rate, retries, and latency, then compute cost per accepted result.
It's boring, and it's the only number that matters.
Step 4: Route by difficulty, not by loyalty
Send the easy bucket to the cheap model and keep the hard bucket on the frontier model. Add a fallback: if validation fails, escalate to the stronger model.
That escalation path is what makes routing safe.
If you want a related read on how people reach for AI tools out of habit rather than measurement, Why Are You Still Paying For This 2 covers a similar instinct from the subscription side.
The Verdict
I don't think the answer is "keep paying for Claude" or "stop paying for Claude." Both are lazy.
The answer is that a flat subscription to one model for every task is the expensive habit, and a hybrid setup will beat it on cost almost every time.
The 40x figure is a ceiling, not an average. You'll approach it on your most repetitive, easily verified workloads. You'll get nowhere near it on the work where a wrong answer costs you an afternoon.
If someone tells you the mystery is solved, ask what they measured. Was it price per token, or price per result that actually shipped?
Where's your own line? Which task did you move to a cheaper model and never regret, and which one did you move back after it burned you?